---
title: How to Run 20+ Agents Comfortably (October 2026)
description: "My practical, temporary setup for running 20+ coding agents across cheap always-on servers: Tailscale, closed ports, herdr, Cloudflare tunnels, backups and monitoring."
date: 2026-07-15
author: Bas Baudoin
tags: [Tech]
url: https://bb-projects.com/blog/run-20-agents-comfortably/
---
# How to Run 20+ Agents Comfortably (October 2026)
> In 6 to 12 months I will probably laugh about this setup. Some open source tool, a new technique, or a smarter agent will do all of it for you. Read this as temporal.
>
> **Updated October 2026:** cmux, tmux and mosh are gone, herdr now does all three jobs. The setup is described by role (personal, business, local, laptop) instead of by machine, because the machines keep changing and the concept does not.
>
> It is heavily inspired by [@levelsio](https://x.com/levelsio)'s tweets. Most of the credit is his, this is just my practical take.
The goal: keep 20+ agents working in parallel, reachable from anywhere including my phone, without babysitting them. Below are the building blocks. The hard technical details you can solve with your own agent.
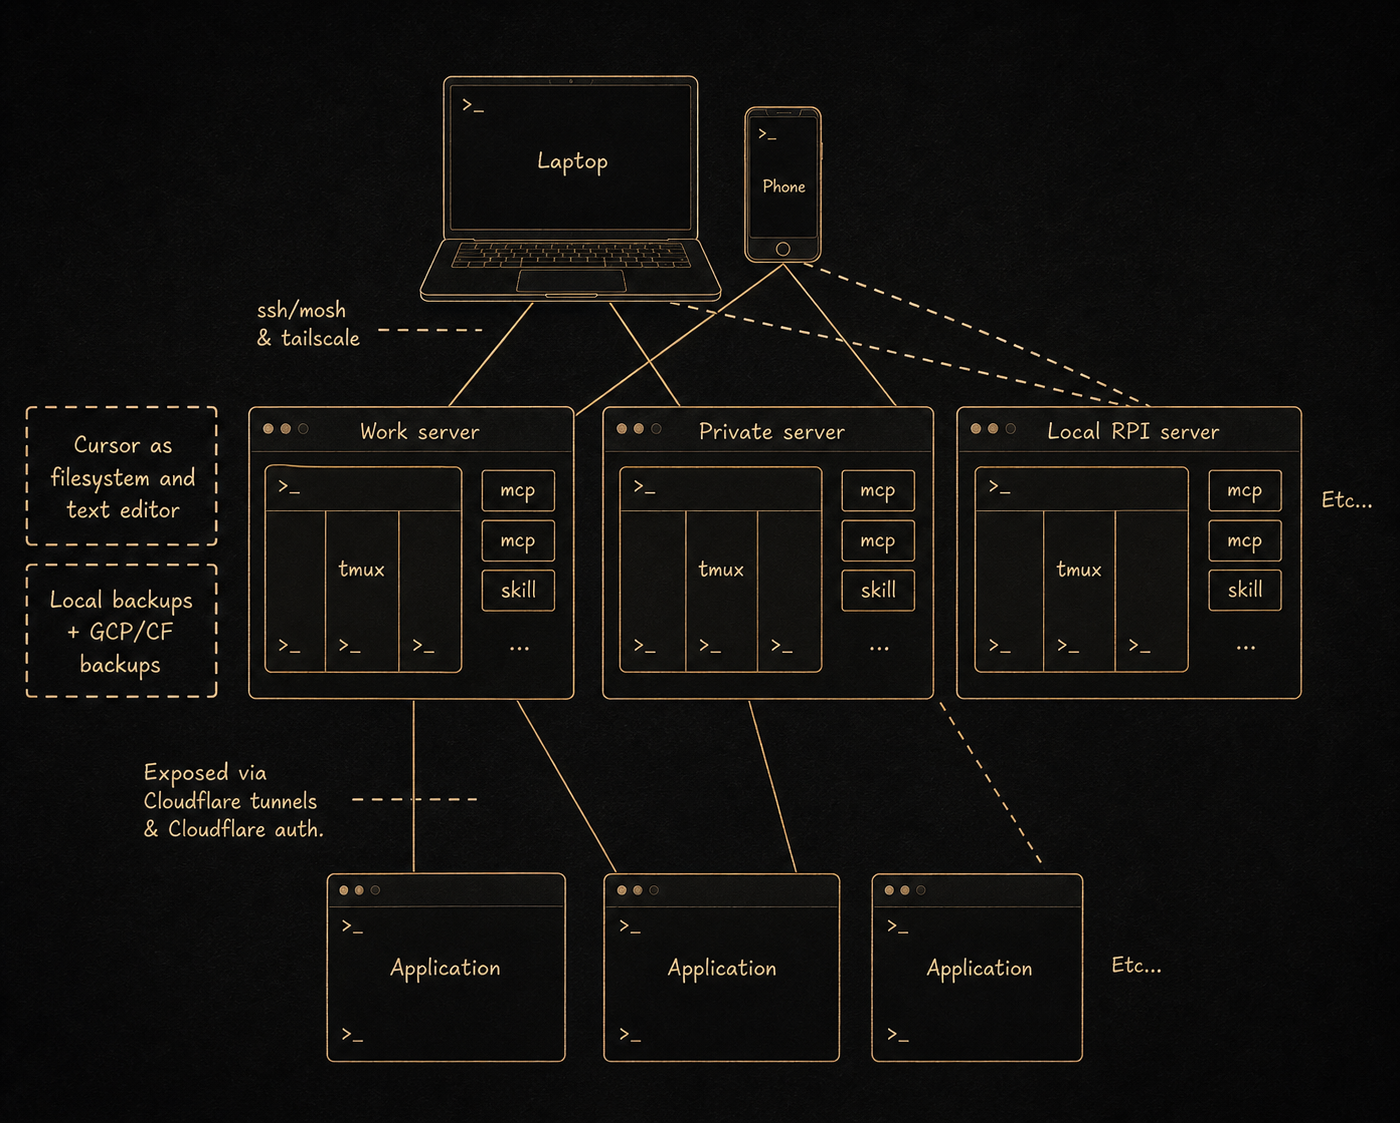
**The shape.** A few cheap always-on machines, split by trust: a personal box, a business box, a local box at home (a Raspberry Pi) and the laptop. The boxes are Hetzner Ubuntu servers or Oracle's free ARM tier, 4GB of RAM is doable, 8GB is more comfortable. OVH Cloud is a fine alternative. Agents run on the servers, not on my laptop. The laptop and phone are just windows into them, so nothing dies when I close the lid or lose signal.
## Access, from anywhere
- **Tailscale.** One private mesh over every machine: servers, laptop, phone. They reach each other by name. This is the backbone.
- **All ports closed.** Firewall everything shut and reach the machines only over Tailscale. Nothing SSH-facing on the public internet.
- **ssh + herdr.** herdr keeps every agent session alive server-side and survives flaky wifi, network switching and sleep. You reconnect and nothing was lost. This is what makes driving agents from a phone actually work, and it replaced both mosh and tmux for me.
- **Provider recovery console.** You will lock yourself out at some point, a bad firewall rule or Tailscale down. The provider's out-of-band console is your way back in. Find it before you need it.
## Running the agents
- **herdr everywhere.** One agent-session runtime on the Mac and on every server. It lets me glance across many agents at once, with one session per project on each box, so every session stays alive server-side. It replaced cmux on the Mac and tmux on the servers.
- **Auto mode on, remote connections always on.** Agents keep going without me clicking approve, and I can reach them from any device.
- **MCP and skills per project.** Each project ships the tools and skills its agents need, so an agent lands ready to work.
- **One config doc.** A single central doc holds the config instructions I push to every server (agent settings, terminal setup), so a new box behaves like the old ones.
- **pm2.** Keeps the apps and long-running processes up across disconnects and reboots.
- **An editor as a filesystem.** I use remotepad, a small SFTP browser and editor I built myself (a DIY Cursor, kind of), to browse the servers over the network and read what the agents actually did.
## Actually operating them
The trick is not the tooling, it is how you move through it. I keep about three agents live per server, each in its own herdr session, and I walk the machines in a fixed loop. Page one is the laptop, page two my personal box, page three the business box, and so on.
Every stop is the same move. Read what the agent just finished, check it, then hand back zero to three follow-up prompts depending on what it needs. The moment it starts working again I leave and go to the next page. By the time I come back around, it has usually produced something new to check.
So there is no single task I am focused on. It is a continuous loop of check and next instruction across all of them. Switching context this hard is not for everyone, but it is the honest answer to how you actually run 20 agents at once instead of babysitting one.
## Exposing the work
- **Cloudflare tunnels for exposed domains.** Public apps dial out through a tunnel, so there are no open inbound ports.
- **Cloudflare Access for protected domains.** An auth wall in front of anything private but remote, so a half-built internal tool is never on the open web.
## Safety net
Agents move fast and delete things, so the backups have to be automatic, encrypted, and actually tested, not aspirational. Three tiers, each catching what the one above misses:
- **Provider snapshot.** Where the provider offers one (Hetzner does), a daily image of the whole box under everything, the coarse net for when a server dies entirely.
- **Litestream.** On the boxes with live databases, it streams them off the box continuously, so the newest writes are never only in one place.
- **restic to Cloudflare R2.** A nightly job on every box that holds data, each to its own R2 bucket: encrypted, versioned, deduplicated, with old snapshots pruned on a schedule. Each host gets its own repo and its own scoped token, so one leaked key cannot touch another box.
On top of the tiers:
- **The database trick.** Before each run I stage every live SQLite database with a proper `.backup`, so restic captures a consistent image instead of a half-written file. If nothing gets staged, the job fails loud instead of quietly backing up nothing.
- **Verified, not assumed.** I test-restored every repo end to end: pull a database back down from R2, run an integrity check, compare it to the live one. This is the layer most people skip, and it is the only one that tells you the backups actually work.
- **Monitoring and push alerts.** Uptime Kuma watches the services and the nightly backups, ntfy pings my phone the moment one falls over. With 20+ agents you will not notice a dead app, or a silently failing backup, by staring at it.
That is the whole thing. Cheap servers, one private network, closed by default, deliberate holes where needed, and a way back in when you lock yourself out.
The drawing at the top stops at "Etc...". Here is the same shape with the etcetera filled in: 20 agents across a personal box, a business box, a local box and the laptop. The names are indicative, yours will be different.
```mermaid
flowchart LR
PHONE["Phone
ssh + herdr, reattach sessions"]
TS{{"Tailscale mesh
every machine by name
all public ports closed"}}
PHONE ==> TS
subgraph LAP["Laptop: herdr + remotepad"]
H0["herdr
glance across all 20"]
A17["17. drafts"]
A18["18. scratch"]
H0 --> A17 & A18
end
TS ==> H0
subgraph BIZ["Business box, 8GB"]
H1["herdr
8 sessions"]
A1["1. api-service"]
A2["2. web-app"]
A3["3. report-builder"]
A4["4. site-crawler"]
A5["5. inbox-triage"]
A6["6. spike"]
A7["7. refactor-bot"]
A8["8. media-encode"]
H1 --> A1 & A2 & A3 & A4 & A5 & A6 & A7 & A8
end
subgraph PER["Personal box, 8GB"]
H2["herdr
7 sessions"]
A9["9. data-pipeline"]
A10["10. knowledge-base"]
A11["11. metrics-tracker"]
A12["12. graph-builder"]
A13["13. note-sync"]
A14["14. tts-render"]
A15["15. backup-verify"]
H2 --> A9 & A10 & A11 & A12 & A13 & A14 & A15
end
subgraph LOC["Local box: Raspberry Pi on the home LAN"]
H3["herdr
1 session"]
A16["16. home-dashboard"]
H3 --> A16
end
TS ==> H1 & H2 & H3
CF["Cloudflare tunnel
dials out, no inbound ports
public domains + Access wall"]
A2 --> CF
A10 --> CF
A16 -. "never exposed" .-> LANONLY["Home LAN only"]
BK["Backups, layered:
provider snapshot, Litestream,
restic to R2, encrypted + verified"]
MON["Uptime Kuma + ntfy
pings my phone"]
A5 --> BK
A13 --> BK
A15 --> BK
A2 --> MON
A10 --> MON
```